Your agent's logs record every task it did: the input, the tools, the answer and what happened next.
But most teams don't keep enough of it, in the right shape, to learn from. So the logs sit there as old model calls. You can't use them to tell whether a cheaper model would do the same work.
Operant turns that record into tests. A past chat becomes a test the moment it's paired with a judgment: this one worked, and this one didn't. A set of graded chats from your own traffic tests the work your product depends on. No public leaderboard can do that.
Pick the work that repeats
Not every chat is worth learning from. Logs hold duplicates, stale instructions, abandoned sessions and behavior you shouldn't copy. So the first job is picking. Operant works out which calls belonged to the same piece of work, from what common agent tools already send. Then it groups the work that keeps coming back.
Keep some chats unseen
Some chats teach, and others must stay unseen. If the chats that taught a cheaper model also grade it, it will always look better than it is. So Operant writes down the split before anything learns. It also enforces one rule: a chat that ever taught can never grade later.
Grade the cheaper model
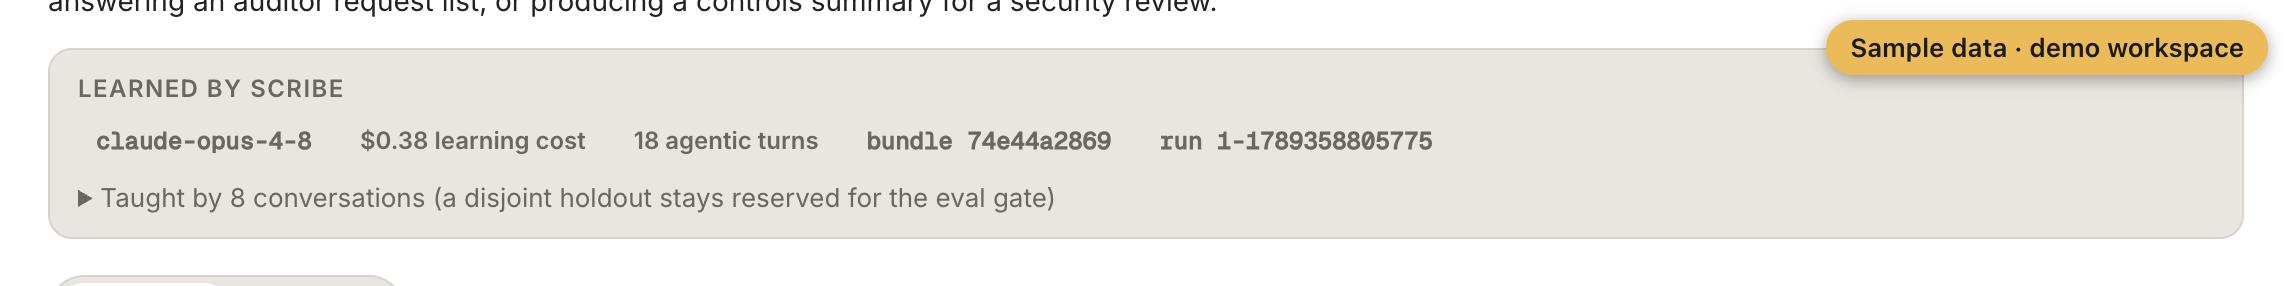
In our published test run, eight chats taught a skill and three were kept aside. A skill is short instructions learned from past chats. The cheaper model with the skill scored 0.9667 against a bar of 0.8, graded against the top model's own answers. A model can't pass by erroring on most of the cases.
The loop
The full loop has these steps:
- Capture the runs.
- Group them into kinds of task.
- Pair them with judgments.
- Split the chats that teach from the chats that grade.
- Score the top model, then test the cheaper one.
- Promote only what passes, with a person's approval.
Turning a change off is always one click, with no test needed.
In the published run, the cheaper model passed on chats it had never seen. Splitting first and keeping the sets apart make a result like that mean something.
So your own past chats become the tests that decide which work can move to a smaller model.
See that test in the live console in How we prove a cheaper model can do the job.